 GLM-Image
Generate Images with GLM-Image
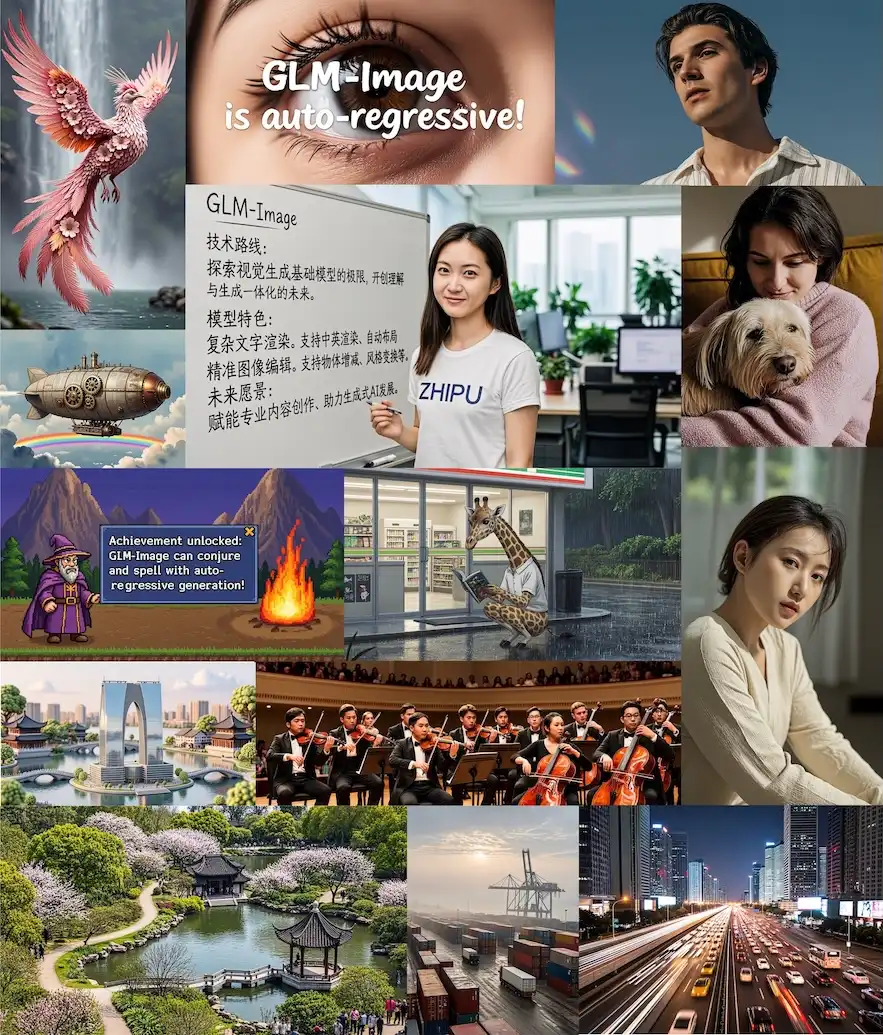
GLM-Image Showcases
View more
An editorial portrait of a dancer in flowing fabric, dramatic rim light, high-contrast monochrome, Vogue-style composition.

Surreal fashion portrait with painted typography reading "GLM-Image", bold graphic poster style, grainy film texture.

Ultra-realistic portrait of a street photographer in backlight, monochrome documentary style, visible film grain. A cinematic close-up of a singer on stage, neon bokeh lights, moody blue and gold palette, shallow depth of field.

Portrait of a cyberpunk guitarist, holographic jacket, rain-soaked alley, vibrant magenta highlights, cinematic atmosphere.

Abstract typographic poster: "CREATE NOW" in bold sans-serif, layered paper textures, lime green accent, modern editorial layout.
Overview
GLM-Image at a glance
A hybrid autoregressive + diffusion model built for text-heavy, knowledge-rich visuals with production-grade deployment options.
16B Parameters
Hybrid architecture with a 9B autoregressive generator and a 7B diffusion decoder.
Text + Image Editing
Native support for text-to-image and image-to-image workflows.
Up to 2048px Output
High-resolution results optimized for print and web.
Open Source
MIT-licensed weights and Apache 2.0 code with local deployment support.
Architecture
Hybrid generation pipeline
GLM-Image separates semantic planning from detail refinement so layout, typography, and texture are optimized independently.
Autoregressive Generator (9B)
Plans semantic layout, composition, and text placement.
Semantic Tokens
256-4096 tokens guide structure before detail refinement.
Diffusion Decoder (7B)
Refines texture, lighting, and text precision at high resolution.
Benchmarks
Text accuracy at scale
GLM-Image leads multi-region text rendering and holds accuracy even as layouts become more complex.
CVTG-2k + LongText-Bench (Jan 2026)
CVTG-2k multi-region text accuracy
Average accuracy across 2-5 text regions.
Regional accuracy trend
Accuracy as text regions increase.
LongText-Bench multilingual accuracy
English vs. Chinese long-text generation.
OneIG quality assessment
Multi-dimensional quality breakdown across models.
Model comparison matrix
Key metrics normalized for quick scanning.
Strengths
Built for text, knowledge, and scale
GLM-Image focuses on rendering accuracy and semantic grounding, ideal for educational, enterprise, and multilingual content.
91.16% multi-region text accuracy on CVTG-2k.
0.9788 Chinese long-text score on LongText-Bench.
Built for diagrams, infographics, and labeled visuals.
MIT weights and Apache 2.0 code for local runs.
Use cases
Where GLM-Image shines
Designed for teams that need clean typography, accurate labels, and dependable multilingual outputs.
Education & Learning
Text-rich diagrams, concept maps, and curricula visuals.
Marketing & Design
Posters, ad creatives, and branded layouts with copy.
Infographics
Charts, timelines, and process flows with precise labels.
Multilingual Content
Localized graphics with consistent typography.
Enterprise Docs
Training materials, SOP visuals, and internal comms.
Creative Concepts
Concept art and experimental layouts with text elements.
Open source & deployable
Run GLM-Image locally with MIT weights and Apache 2.0 code. Keep data private while scaling to production workloads.
- Local inference with full privacy control
- Flexible hosting for enterprise compliance
- Transparent architecture for research teams
Know the trade-offs
Aesthetic-first imagery
GLM-Image prioritizes text accuracy and knowledge details over pure style.
Knowledge retrieval
Best results come from detailed prompts or external knowledge input.
Get started
Build with GLM-Image today
Generate text-rich visuals, edit with reference images, and ship production-ready outputs in minutes.
Frequently Asked Questions
Everything you need to know about our platform